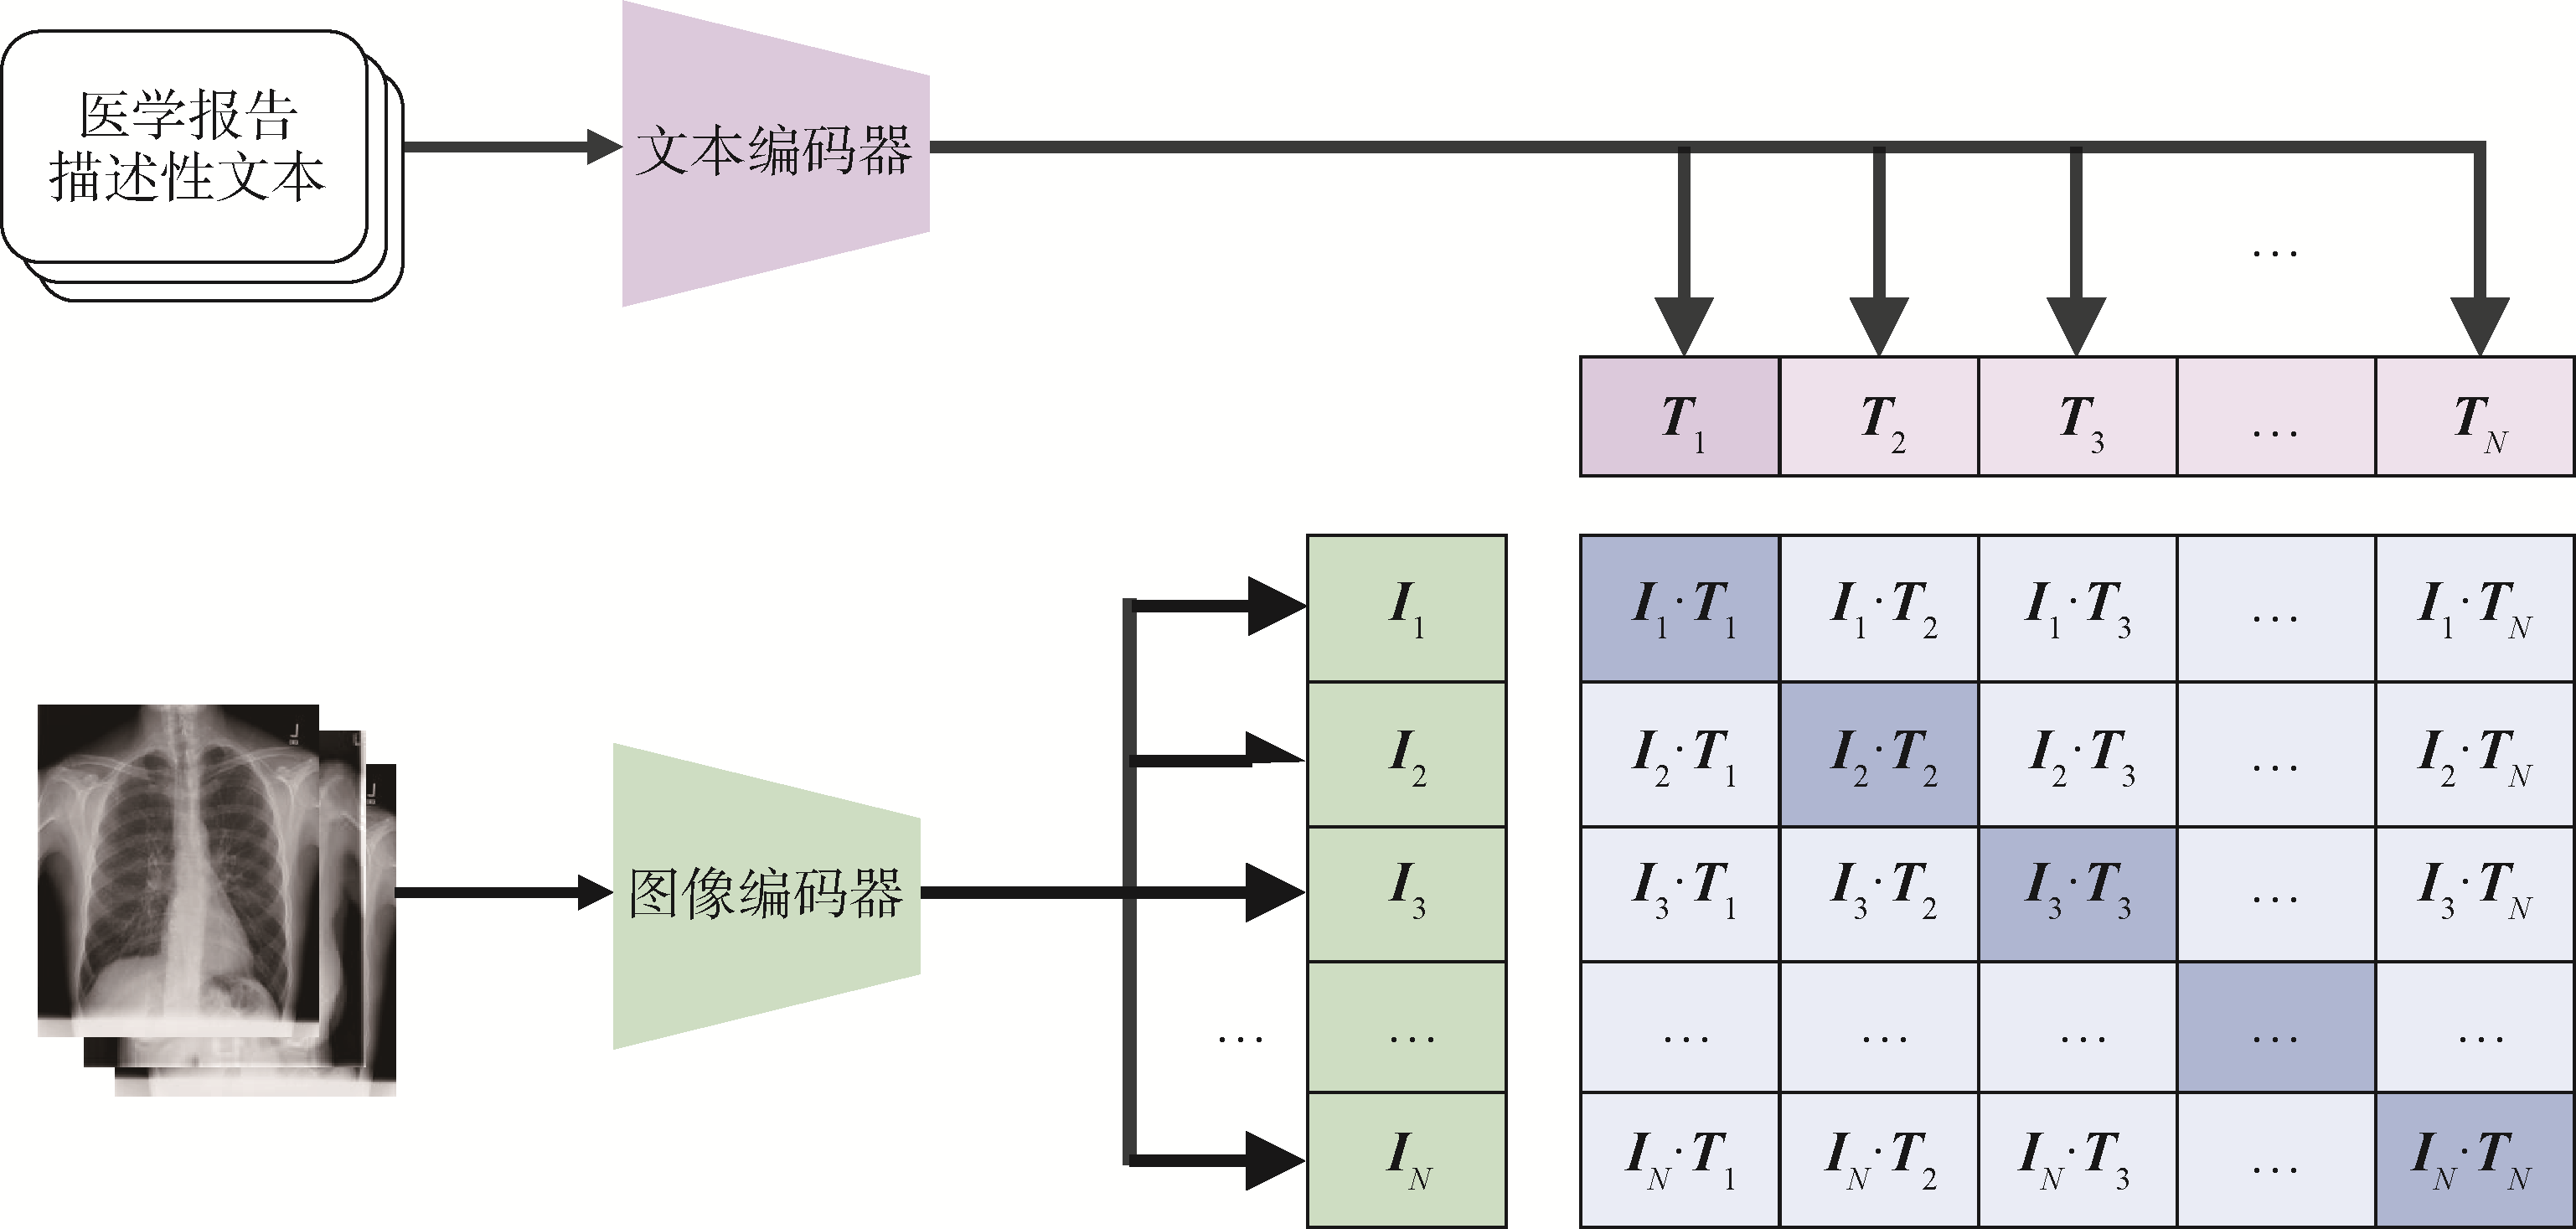
[Objective] This study provides a systematic review of the methodological evolution and research advances in Medical Image Report Generation in the context of generative artificial intelligence, with the aim of providing a reference for future research and development in this field. [Coverage] Literature searches were conducted in Google Scholar, ScienceDirect, PubMed, IEEE Xplore, Springer, and CNKI using Chinese and English search terms, including ‘Medical Image Report Generation’, ‘Generative Artificial Intelligence’, ‘Deep Learning’, ‘Pre-Trained Language Model’, and ‘Multimodal Large Language Model’. A total of 104 representative papers were selected. [Methods] Focusing on research advances in Medical Image Report Generation in the context of generative artificial intelligence, this study establishes a systematic classification framework based on technological evolution. It traces the development of the field from early approaches to multimodal large language models, compares the performance of representative models across multiple mainstream metrics on benchmark datasets, discusses existing challenges, and identifies future research directions. [Results] Existing methods have made continuous progress in cross-modal semantic fusion, language generation quality, and semantic consistency, advancing Medical Image Report Generation from descriptions of key information toward high-quality textual reports with complete structures and standardized terminology. [Limitations] Trade-offs were made between the depth and breadth of the review, and methodological differences among the included studies may introduce certain limitations to the analysis. [Conclusions] Future research should focus on improving the generalizability, output accuracy, and interpretability of Medical Image Report Generation models; developing high-quality data resources and standardized evaluation metrics; strengthening privacy protection and ethical review mechanisms; and promoting model validation and deployment in real-world clinical settings, thereby facilitating their further application in intelligent healthcare.
[Objective] This paper aims to reveal the formation process of intelligent informetrics, and call for seizing the development opportunities of intelligent informetrics, and provide methodological reference for subsequent scholars. [Coverage] A search strategy was developed around the application of AI in the field of informetrics, and searches were conducted in the Web of Science and CNKI databases. After data refinement and citation searching, a total of 326 Chinese and English publications were finally identified. [Methods] Through systematic searching and close reading of the literature, this paper reviews and elaborates in detail the progress of AI technology applied to identification, prediction, and classification in the field of informetrics at home and abroad over the past decade. [Results] In terms of identification applications, AI is mainly used for paper identification and fine-grained entity identification. In terms of prediction applications, AI is mainly used for predicting paper impact, scholar impact, and research trends. In terms of classification applications, AI is mainly used for classifying papers by discipline, by content, and by sentiment and motivation. Through careful summarization and interpretation, the principles and processes of AI application in each direction are revealed. [Limitations] Core literature was screened manually, and not all publications on this topic were analyzed. [Conclusions] Leveraging AI technology to address complex problems in the field of informetrics has become an inevitable trend, and proficiency in applying AI technology has become a key competency in the field of informetrics.
[Objective] To address sentiment semantic sparsity and reduce noise interference in multimodal sentiment analysis, this paper proposes a multimodal sentiment analysis method based on Chain-of-Thought (CoT)-enhanced large language model (LLM) information augmentation and conditional information fusion. [Methods] First, a text-image dual-channel CoT prompting template is constructed to guide the LLM in generating auxiliary information highly relevant to sentiment semantics, thereby enhancing the semantic representation of the input data. Second, Transformer encoders with conditional normalization are employed to separately fuse the original text and image features with their corresponding generated auxiliary information. Finally, a cross-modal attention mechanism is applied to integrate multimodal information for sentiment classification. [Results] The proposed method achieves higher accuracy and Macro-F1 scores than baseline models on both the Twitter-2015 and Twitter-2017 public datasets. Specifically, on the Twitter-2015 dataset, it outperforms the best-performing baseline for each individual metric by 1.59 percentage points in accuracy and 2.12 percentage points in Macro-F1; on the Twitter-2017 dataset, it surpasses the best baseline for each individual metric by 1.67 percentage points in accuracy and 2.93 percentage points in Macro-F1. [Limitations] The effectiveness of the method has not yet been validated on a broader range of multimodal sentiment analysis datasets. [Conclusions] The proposed method can effectively enrich sentiment semantic information and fully integrate image and text features, thereby improving the performance of multimodal sentiment analysis.
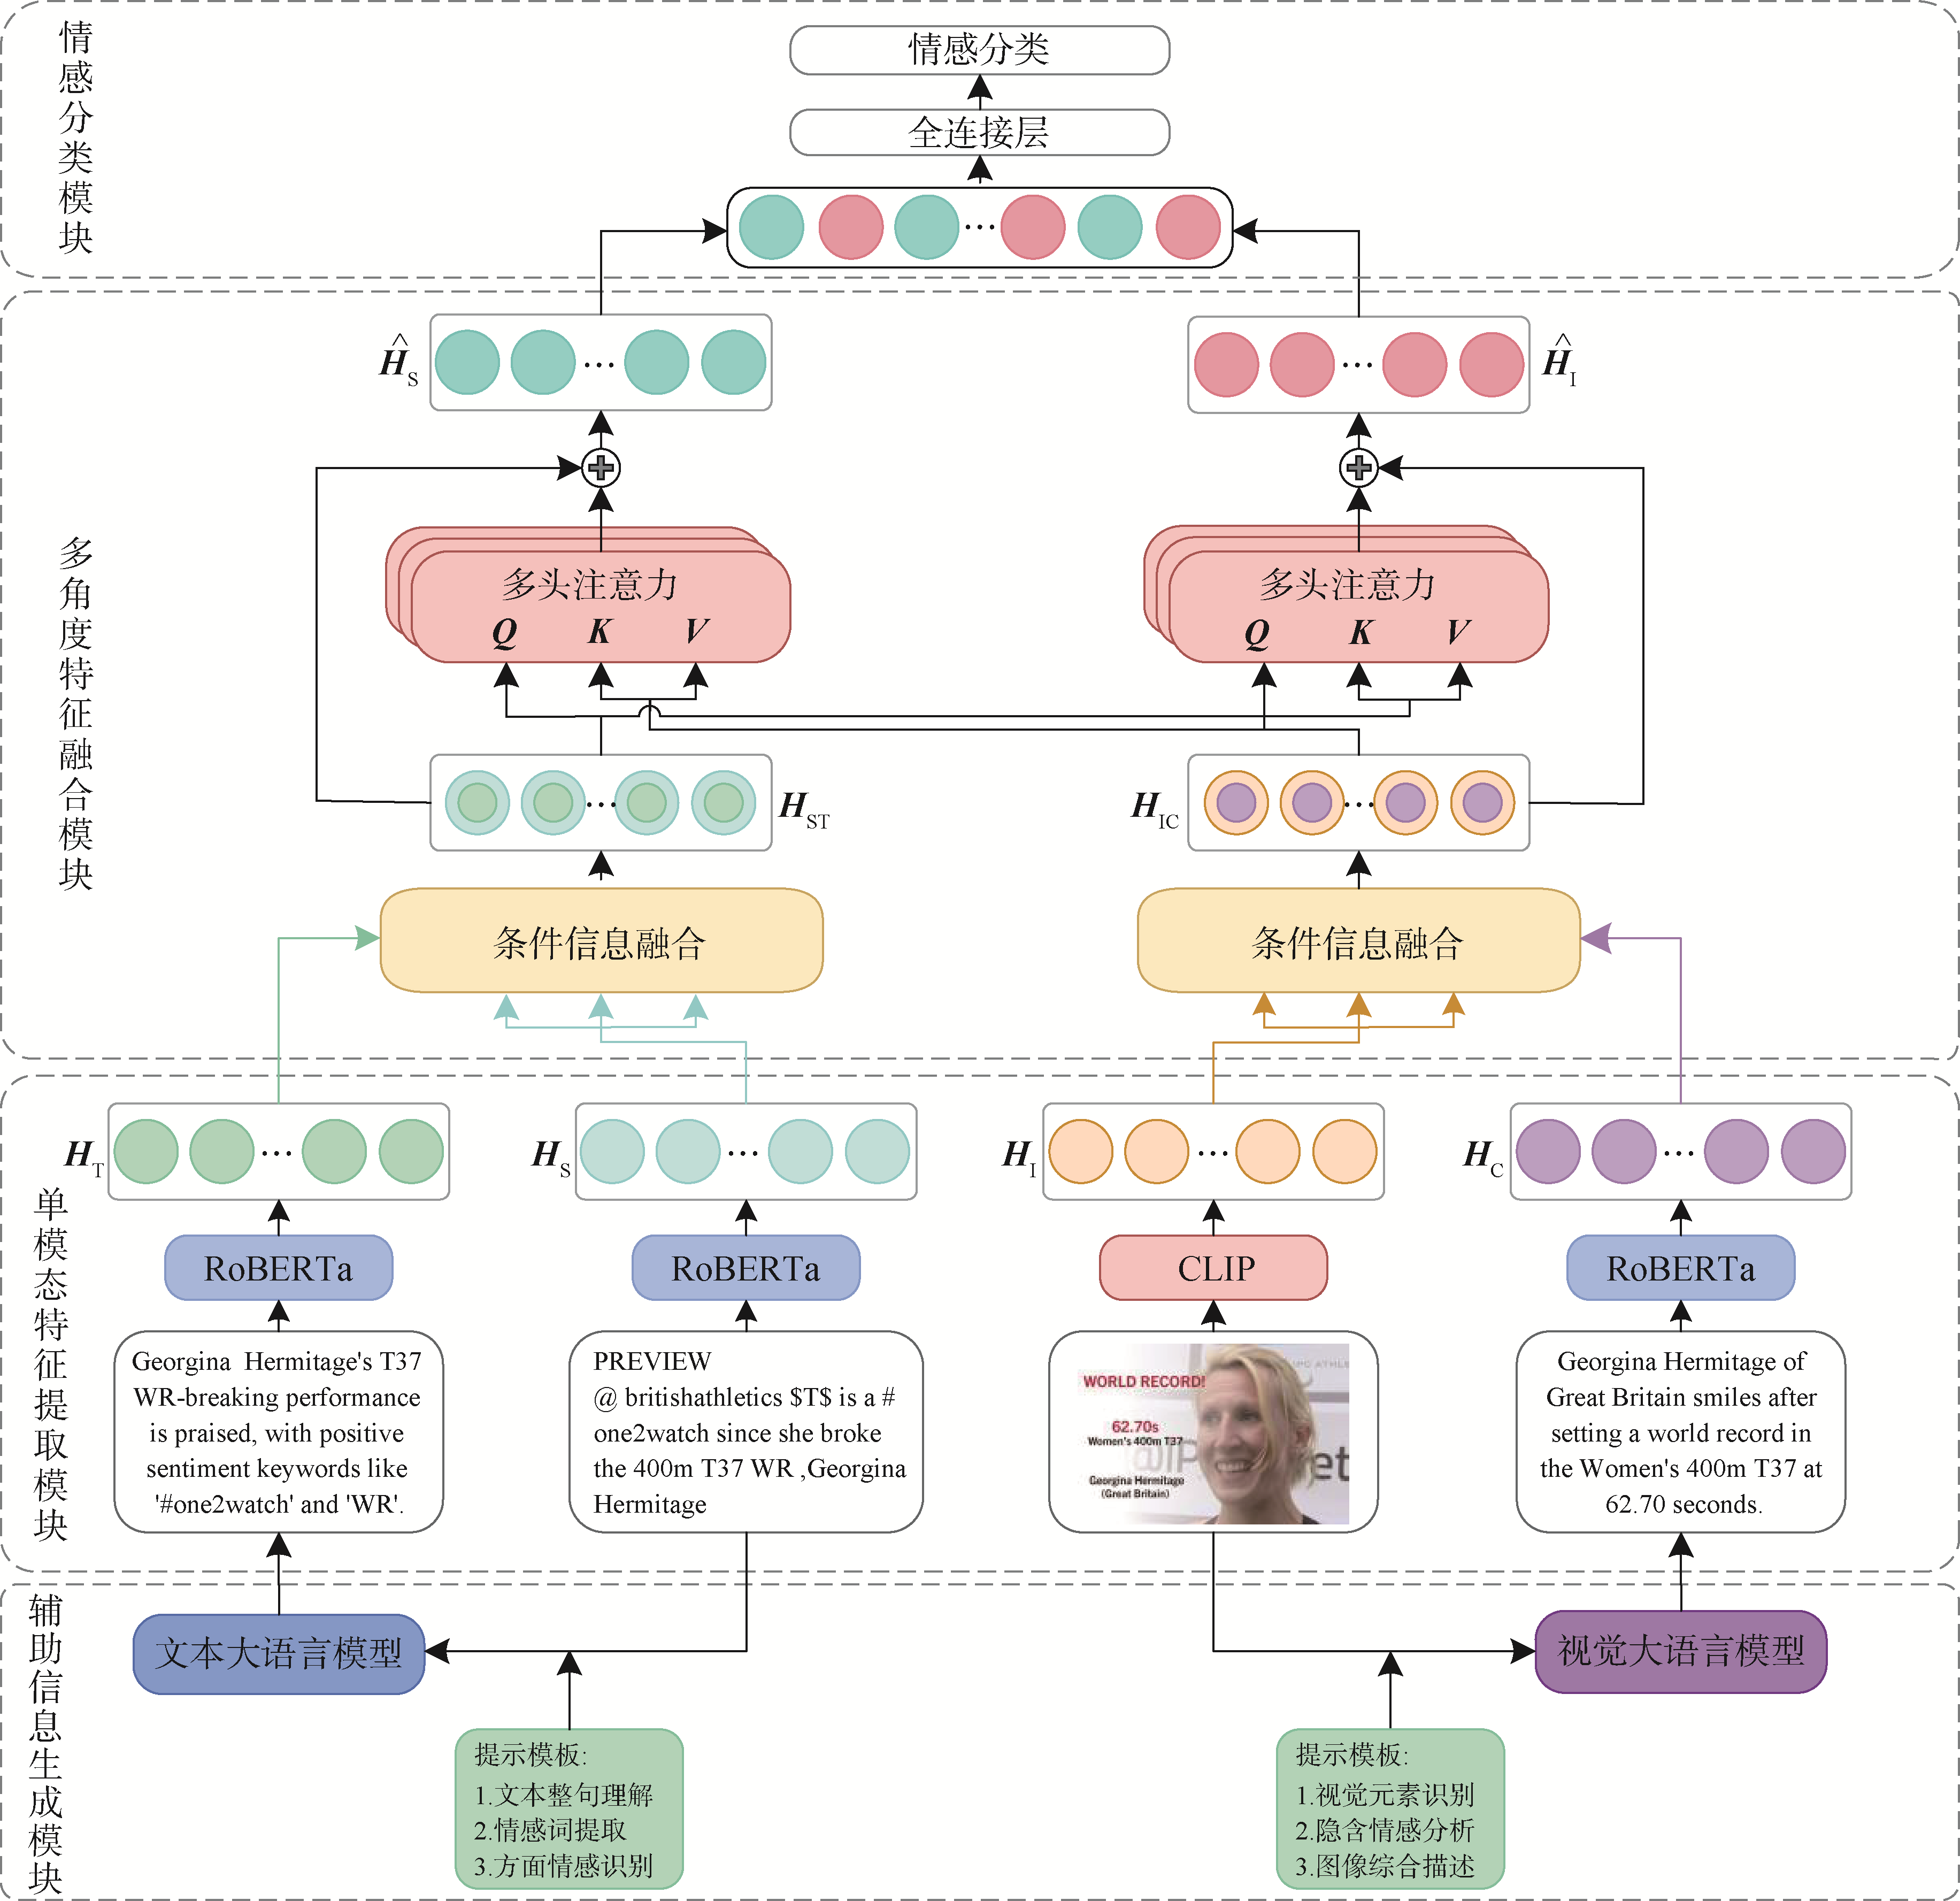
[Objective] To mitigate the constraints imposed by the inherent semantic gaps among heterogeneous modalities on cross-modal fusion efficiency and sentiment recognition performance, this study proposes a multimodal sentiment analysis method integrating a semantic harmonization network with a large language model (LLM-Harmony). [Methods] Multimodal large language models (MLLMs) are employed to generate emotion description texts, which are subsequently enhanced using a gated memory network to highlight sentiment-relevant information while filtering out redundant information. A cross-modal attention network is then used to deeply integrate the original modality features with the enhanced emotion descriptions, thereby reducing semantic distribution discrepancies across modalities. During the fusion stage, a text-centered hierarchical fusion network is designed to guide multimodal information integration from two complementary perspectives: modality-specific information, which captures distinctive sentiment details, and modality-shared information, which captures consistent sentiment cues across modalities, thereby enabling comprehensive capture of multimodal information. [Results] The proposed method outperforms the baseline models on the public CMU-MOSI and CH-SIMS datasets. In terms of fine-grained sentiment classification metrics, compared with DEVA, LLM-Harmony improves Acc-5 and Acc-7 on CMU-MOSI by 3.55 and 1.71 percentage points, respectively, and improves Acc-3 and Acc-5 on CH-SIMS by 2.82 and 6.05 percentage points, respectively. [Limitations] The use of MLLMs to generate emotion descriptions in the semantic harmonization network incurs additional computational overhead. [Conclusions] The proposed method effectively bridges the semantic gaps among heterogeneous modalities and substantially improves the performance of multimodal sentiment analysis.

[Objective] To improve the interpretability and implicit sentiment analysis capabilities of aspect-based sentiment analysis (ABSA) models, this study proposes an explainable ABSA method that combines supervised fine-tuning (SFT) with reinforcement learning. [Methods] First, a reasoning dataset was constructed using DeepSeek-R1; next, Qwen2.5-7B-Instruct was fine-tuned using SFT, and a composite reward function combining rewards for output format, answer format, and sentiment classification correctness was designed; finally, the model was trained with reinforcement learning using the Group Relative Policy Optimization (GRPO) algorithm. [Results] On the Restaurant14 dataset, the proposed method achieved an F1 score of 90.22%, 1.26 percentage points higher than that of MT-ISA; on the Laptop14 dataset, it achieved an implicit sentiment classification accuracy of 91.75%, 3.18 percentage points higher than that of MT-ISA. After training on the respective Chinese datasets, the model achieved F1 scores of 84.63% on Lasted and 91.55% on OHC. [Limitations] Experiments were limited to aspect-based sentiment classification and did not cover more complex tasks, such as sentiment information extraction. [Conclusions] The proposed method improves implicit sentiment classification accuracy, enhances the interpretability of sentiment classification results, and demonstrates robust performance on Chinese and English datasets; a well-designed composite reward function is crucial for model optimization.

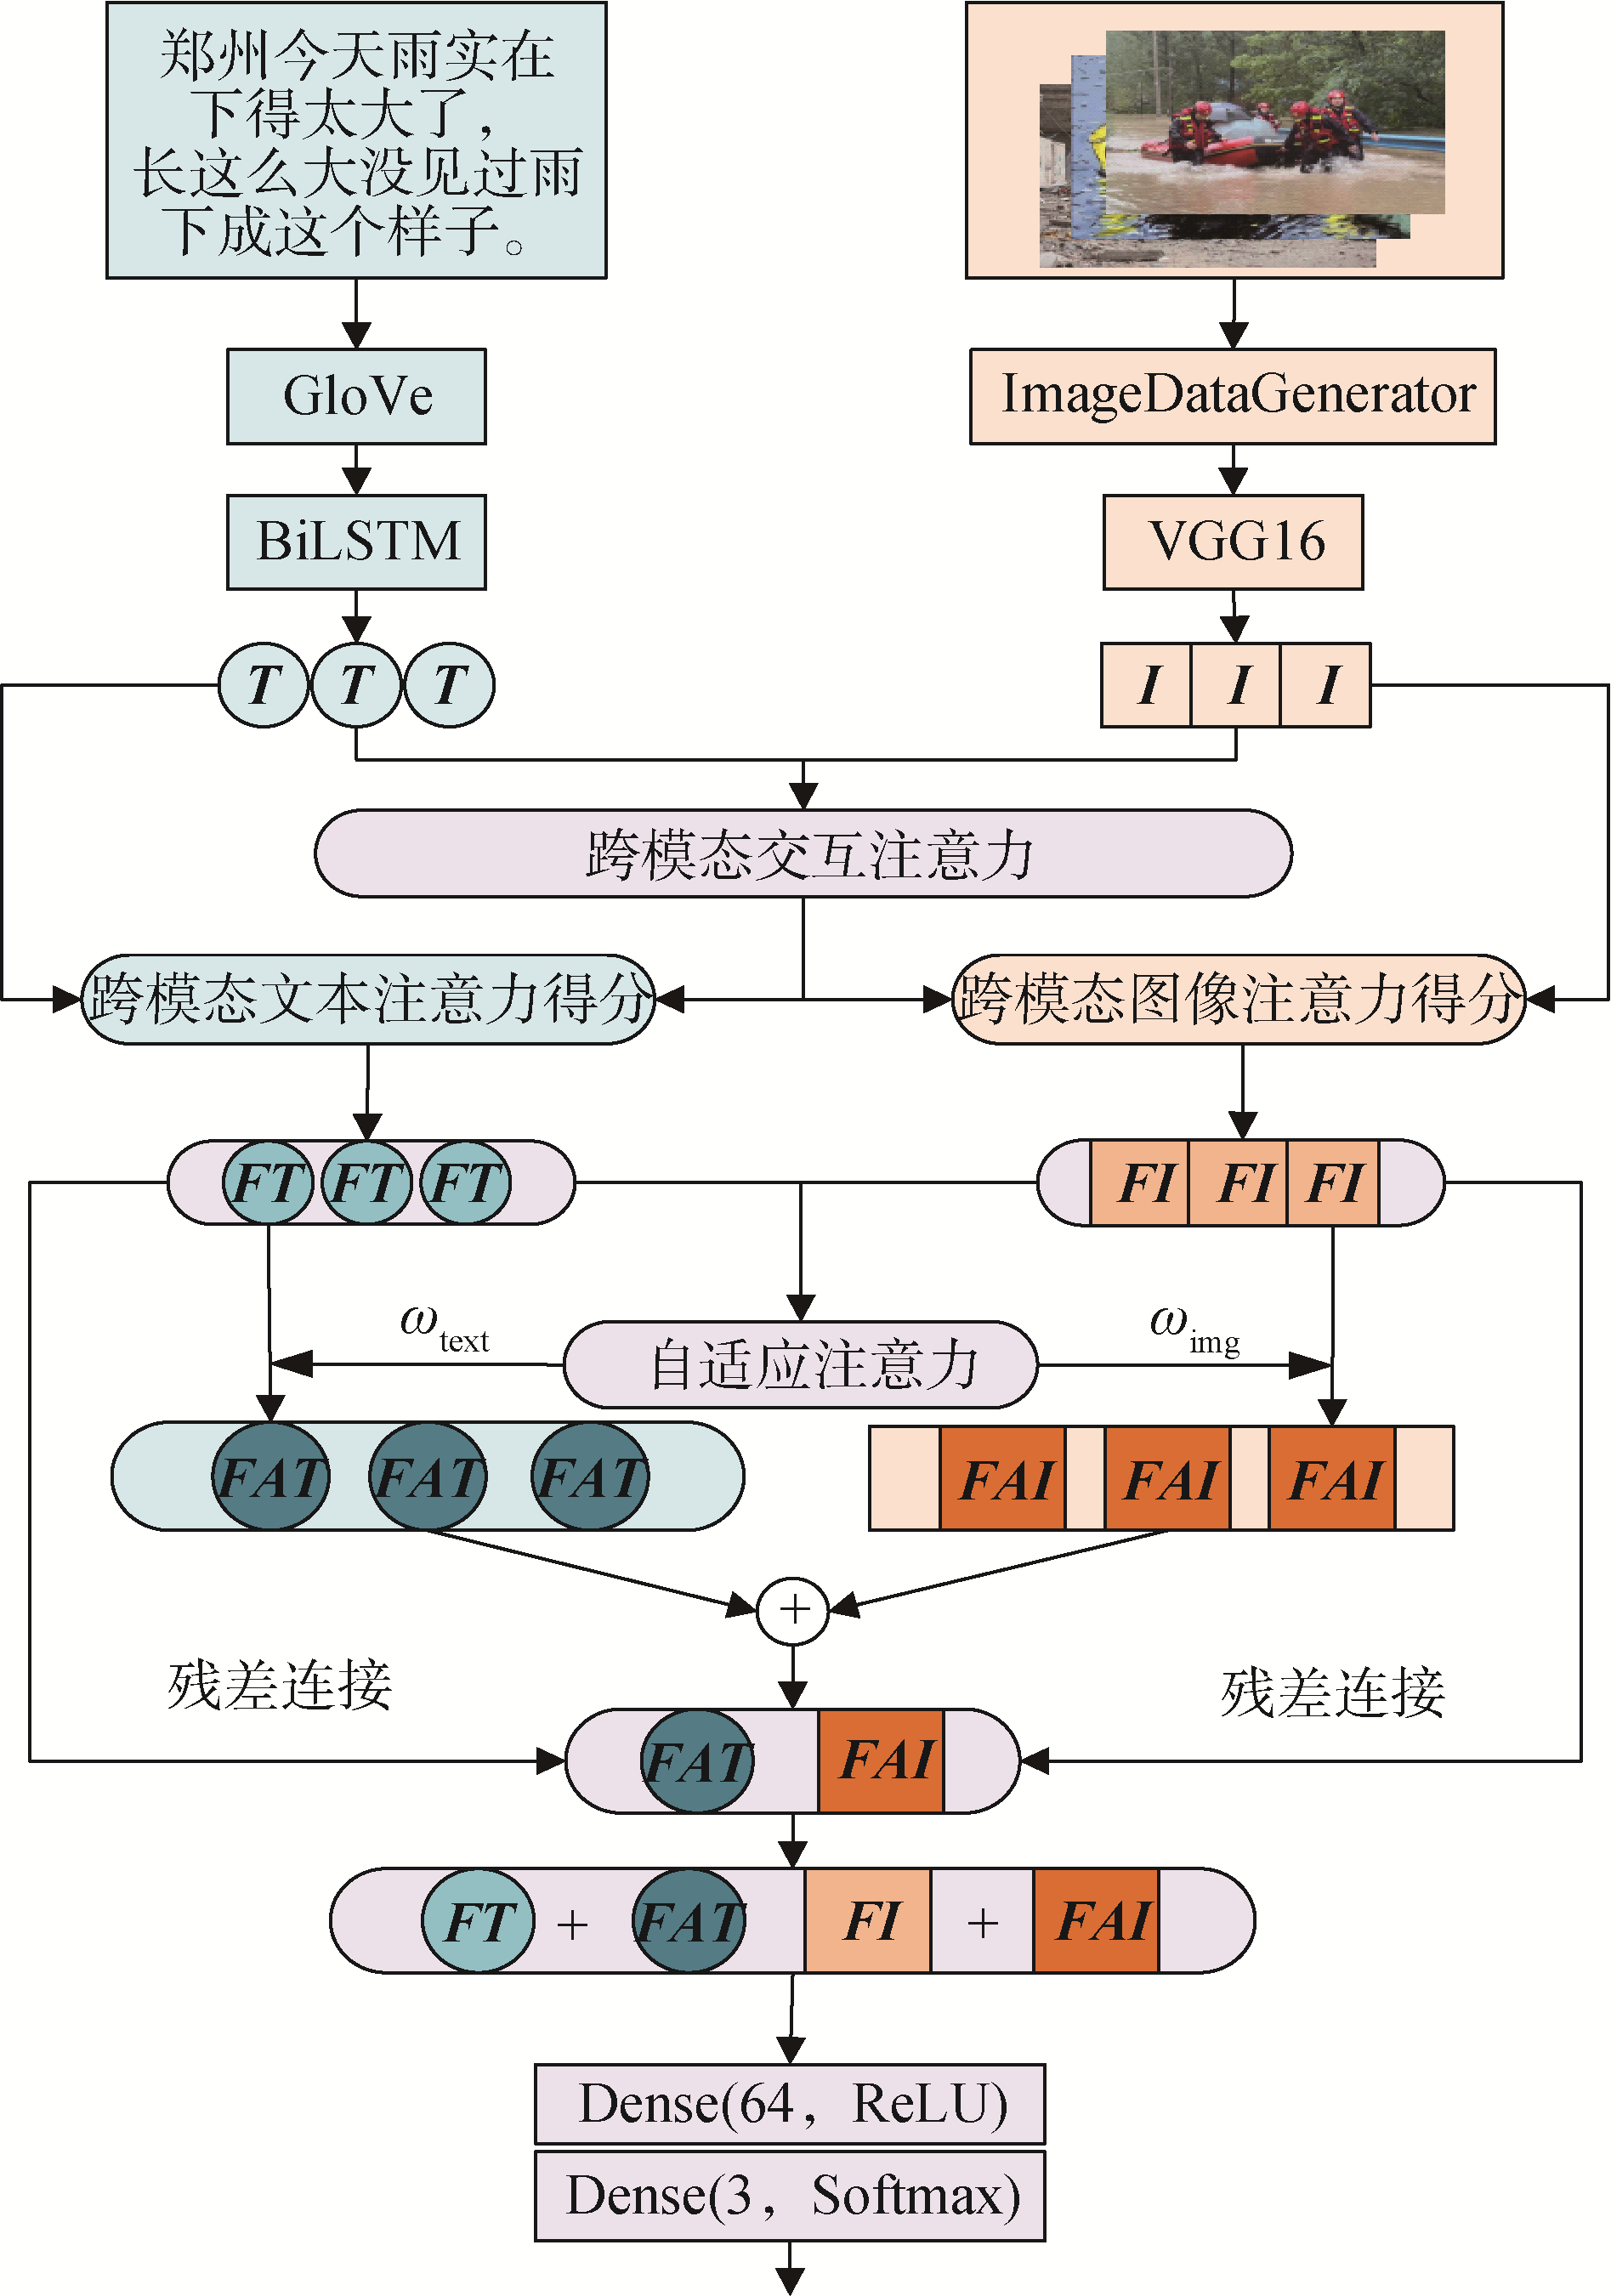
[Objective] Existing sentiment analysis of public opinion on emergency network suffers from two understudied issues: imbalanced image-text data volume and insufficient cross-modal interaction modeling. This paper proposes a sentiment analysis model for emergency network public opinion based on adaptive cross-modal fusion attention to address these limitations. [Methods] First, image enhancement techniques are employed to align image features with text data for public opinion on emergencies. Next, a two-stage cross-modal interactive attention mechanism is introduced to capture the deep correlations between image and text modalities in emergency network public opinion, enhancing the complementary information across modalities. An adaptive attention mechanism is then employed to dynamically assign weights based on the contribution of each modality to emotion recognition, achieving effective cross-modal feature fusion. Finally, residual connections are incorporated to process the fused features, thereby improving the model’s generalization capability. [Results] The model is applied to sentiment analysis of public opinion concerning three emergency events. Three groups of comparative experiments show that the model achieves an overall accuracy of 93.68% and an overall recall rate of 93.15%. [Limitations] This study focuses on the interactions between image and text modalities. Future research could integrate video data and additional heterogeneous modalities to support more comprehensive sentiment analysis. [Conclusions] The proposed model effectively captures the interaction between image and text features in emergency network public opinion, enabling dynamic cross-modal fusion. It optimizes gradient propagation and information flow, maintaining strong performance in deep networks and improving the accuracy of multimodal sentiment analysis of public opinion concerning emergency events.
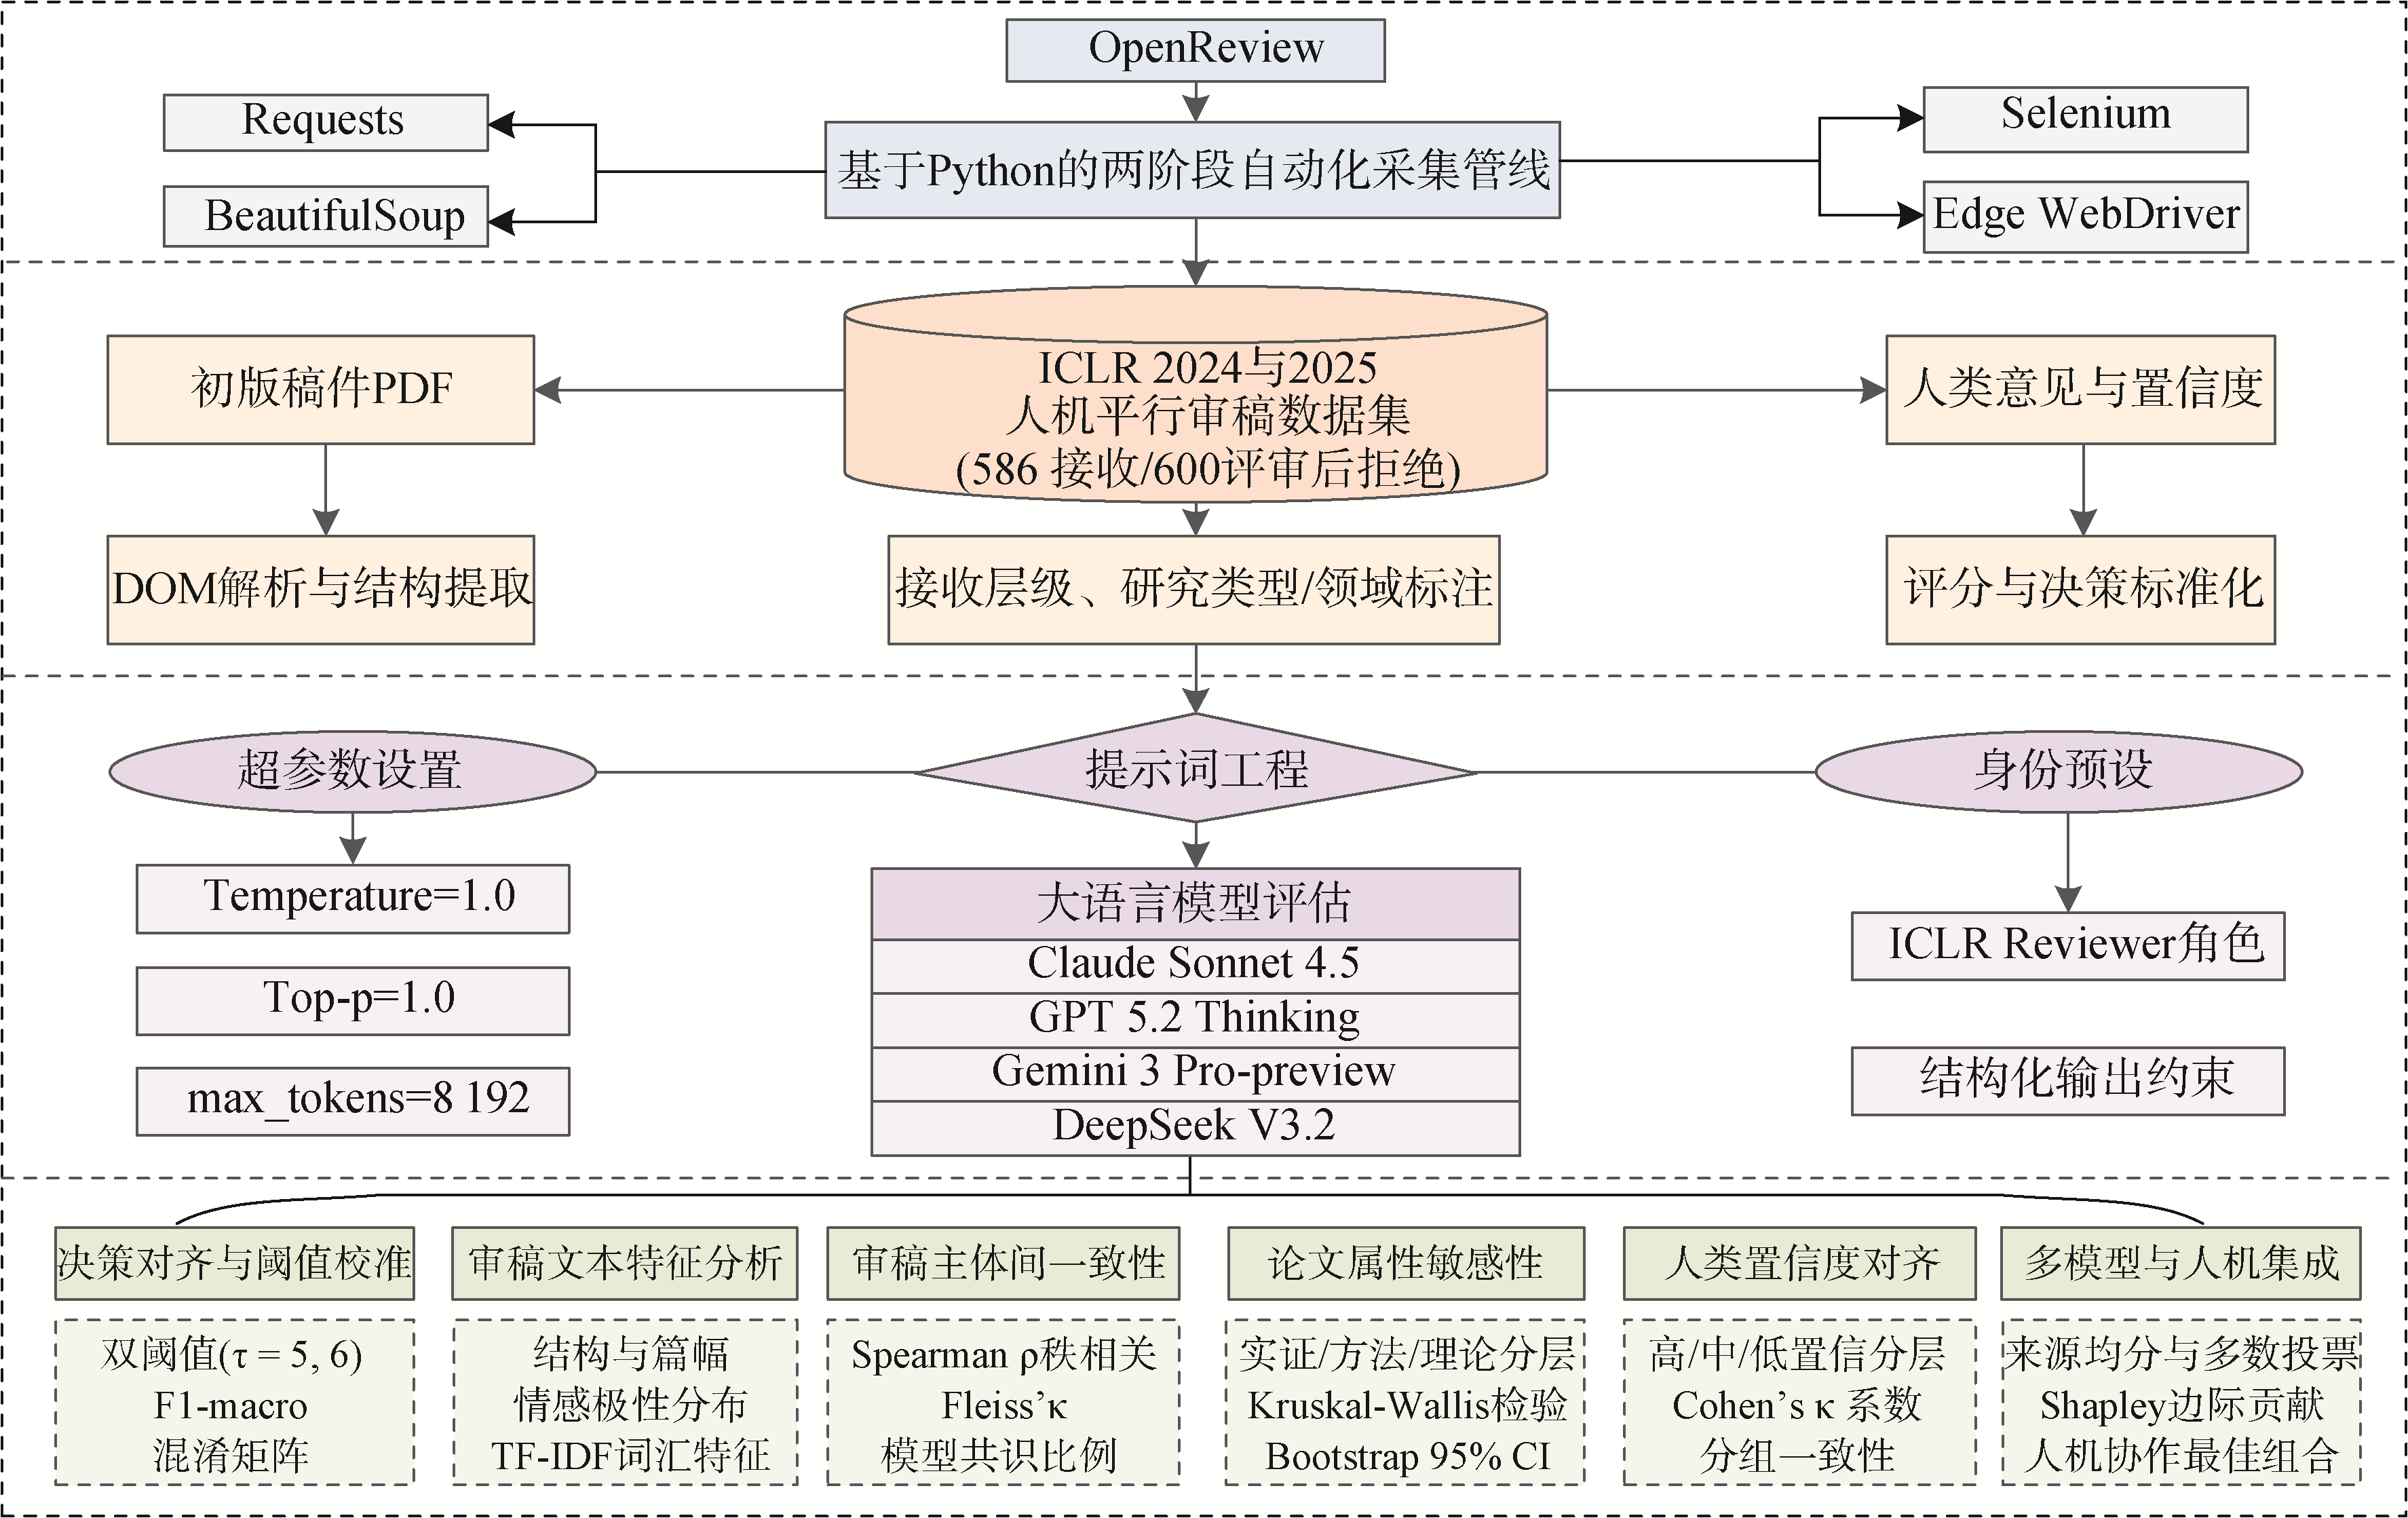
[Objective] To examine biases in review scores generated by large language models (LLMs) and the effects of score calibration, and to evaluate the influence of multi-model ensembles and human-AI collaboration on alignment with acceptance decisions. [Methods] Using peer reviews from the 2024 and 2025 International Conference on Learning Representations (ICLR), this study compared four LLMs in terms of decision alignment, textual characteristics, inter-reviewer agreement, and human-AI collaboration, based on 4,655 human reviews and 18,620 AI-generated reviews. [Results] Raw LLM scores generally exhibited upward bias and compressed differentiation across acceptance tiers, resulting in a tendency toward over-acceptance under the standard threshold. Threshold calibration substantially improved alignment with actual acceptance outcomes. Although LLM-generated reviews approached human reviews in structural completeness and linguistic organization, they remained weaker in depth of critique, sentiment differentiation, and discrimination among quality tiers. After threshold calibration, the best-performing human-AI strategy achieved the highest accuracy of 0.964, exceeding the best single LLM by 0.073. [Limitations] This study used data from only the 2024 and 2025 editions of ICLR; limitations in sample coverage and model versions may affect the generalizability of the findings. [Conclusions] At present, LLMs cannot replace human reviewers in conducting independent peer review, but they can serve as an important component of review assistance and human-AI collaborative evaluation.
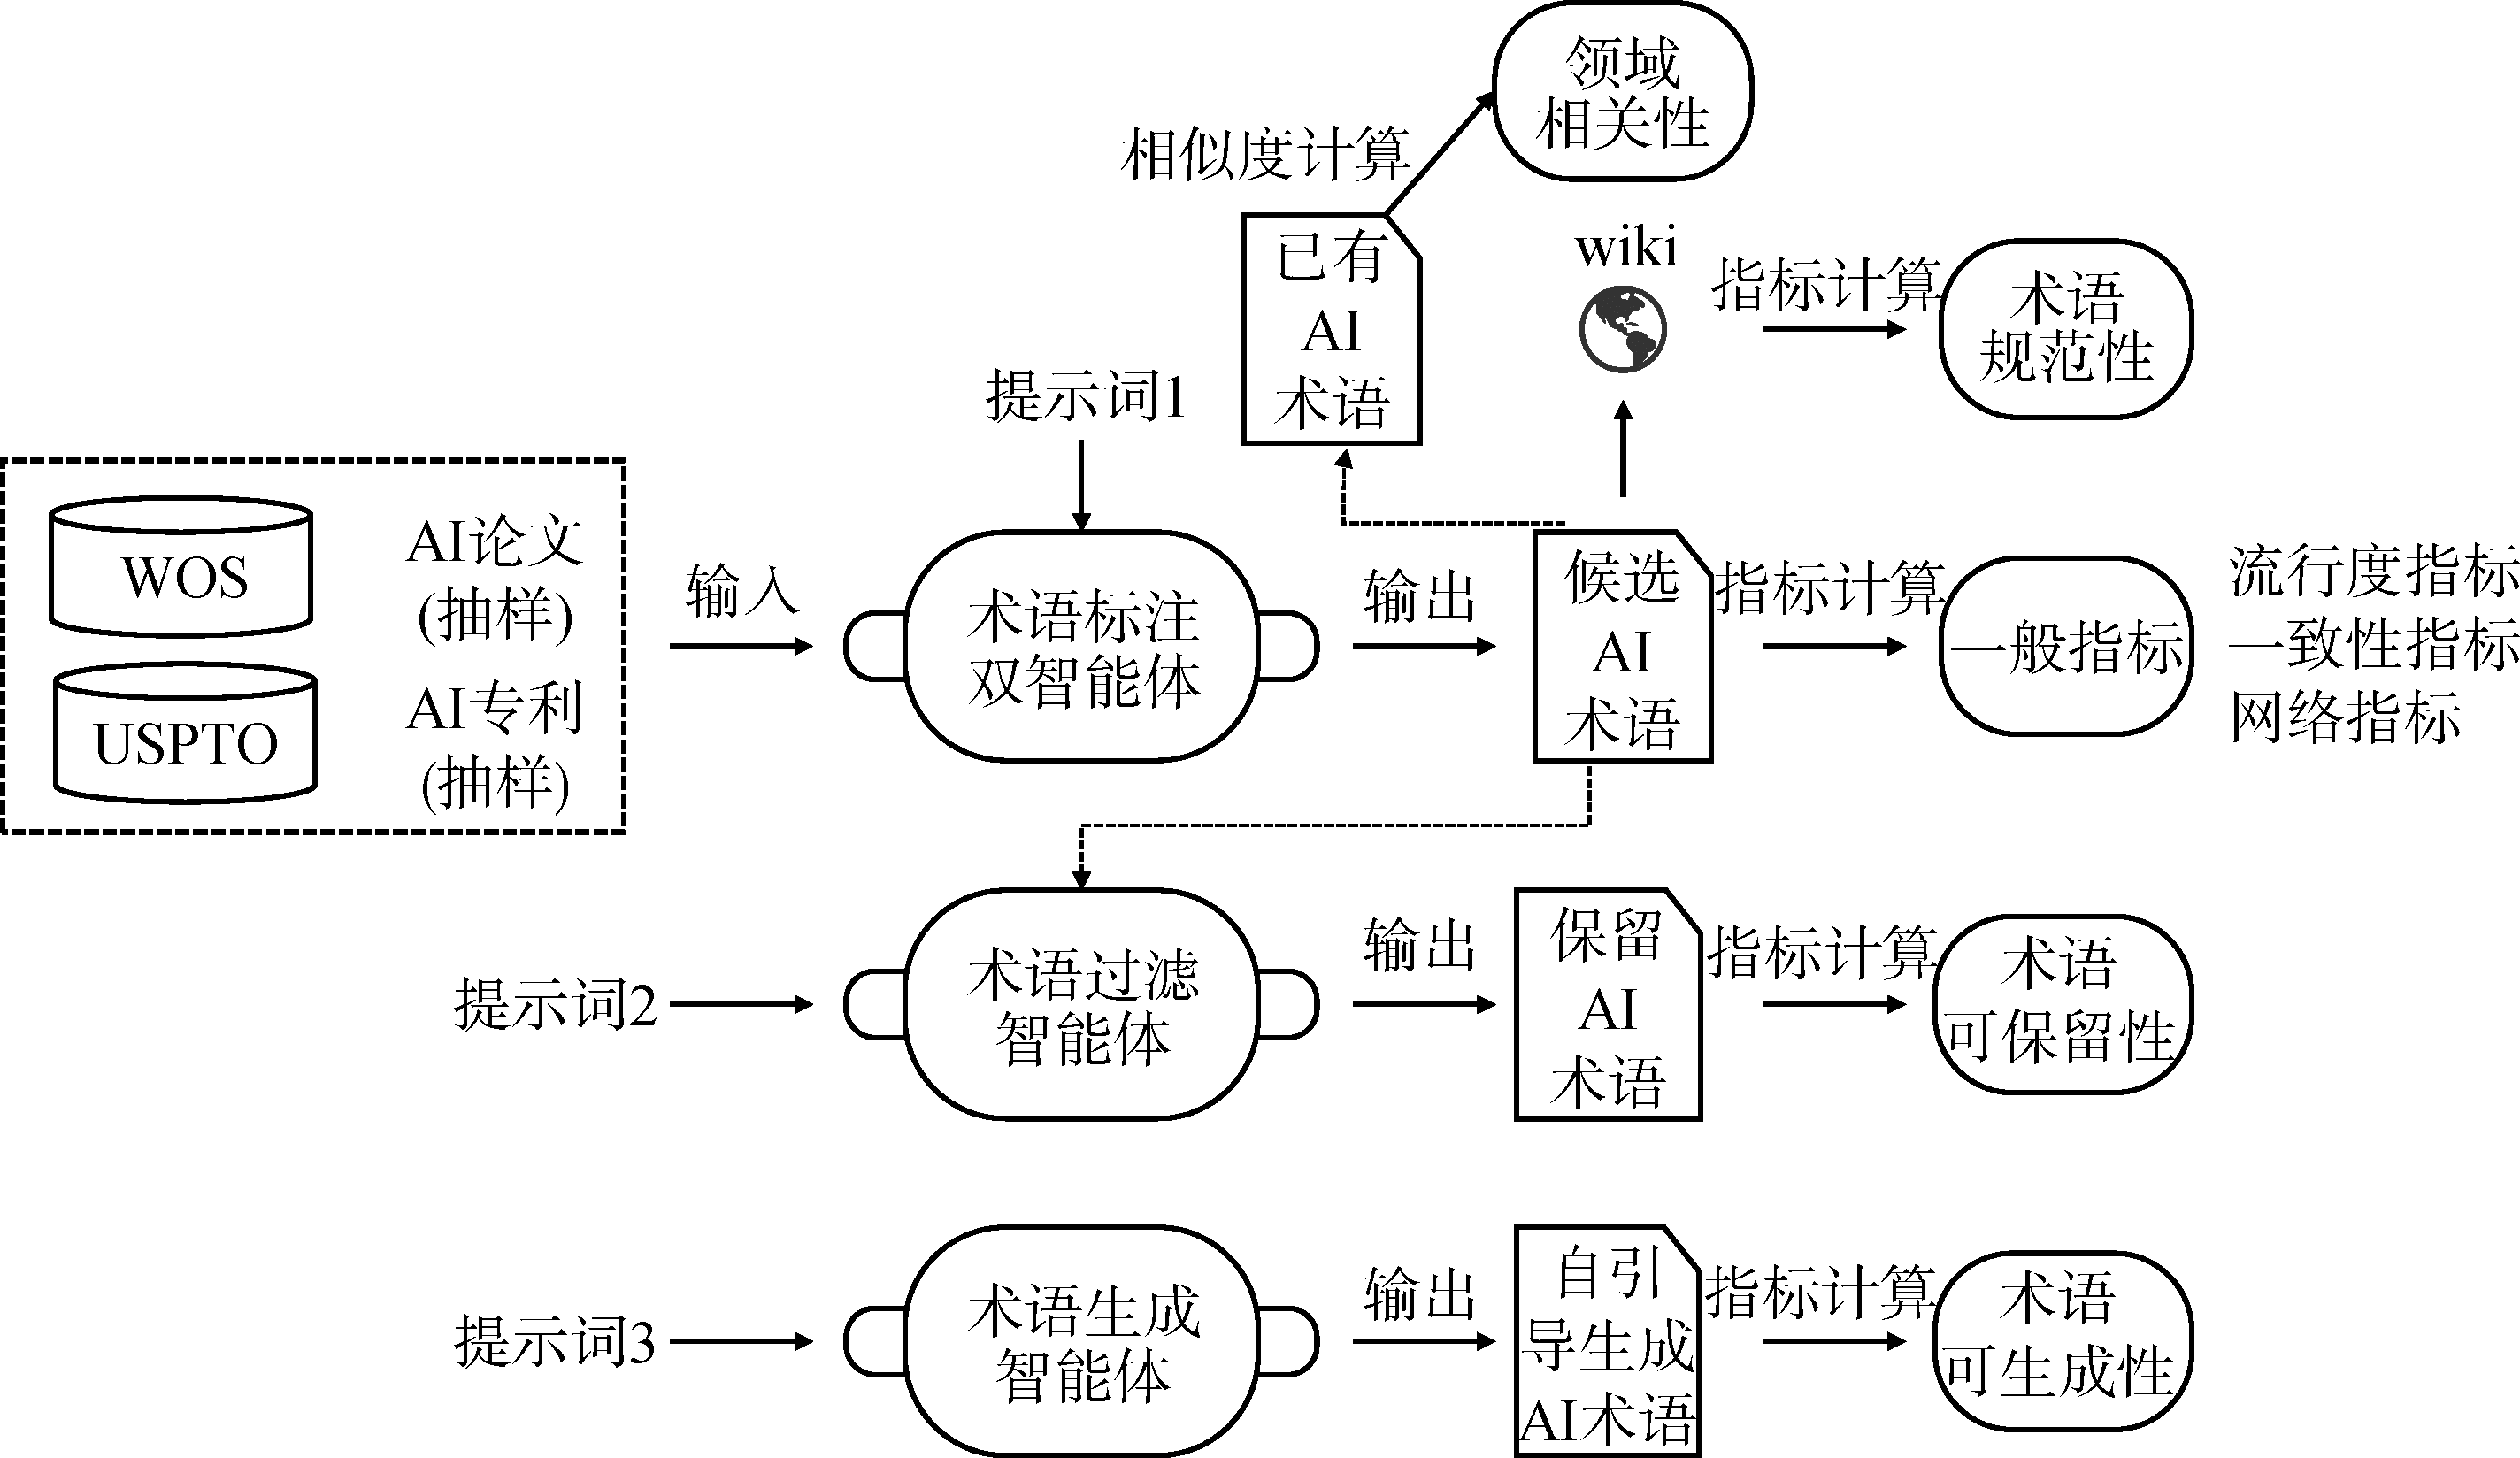
[Objective] This study proposes a terminology extraction method based on multi-agent collaboration and hybrid metric evaluation, aiming to alleviate hallucination issues and interpretability challenges in large language model (LLM)-based terminology extraction, and to construct a high-quality artificial intelligence (AI) terminology set. [Methods] A heterogeneous dual-agent framework (DeepSeek V3 and GPT-4o Mini) is employed to collaboratively extract candidate AI terms. A hybrid metric evaluation system is further developed by integrating unithood, termhood, and multi-agent consistency, enabling hierarchical scoring and ranking of extracted terms. Experiments are conducted on large-scale academic publication and patent corpora, and the effectiveness of the proposed method is validated through expert evaluation and ablation studies. [Results] Experimental results based on expert annotations show significant inter-group differences across term quality levels. The Kruskal-Wallis H statistics for domain relevance and lexical specificity reach 98.05 and 94.26, respectively (P-value<0.001). Ablation studies further indicate that removing agent-collaboration-related indicators leads to an average reduction of approximately 17 percentage points in correlation with expert judgments. [Limitations] This study does not employ high-performance large language models and does not cover the full corpus, which may lead to the omission of certain terminology characteristics. [Conclusions] The hybrid metric evaluation framework effectively distinguishes term quality levels, enabling the filtering of low-quality terms. The multi-agent collaboration mechanism plays a distinctive role in enhancing the discriminative capability of the evaluation metric system in distinguishing term quality levels.
[Objective] To address information overload caused by the rapid growth of academic literature, as well as the limitations of traditional recommender systems in terms of semantic understanding and explainability, this study proposes an academic literature recommendation framework that integrates large language models (LLMs) with graph augmentation, aiming to provide a more accurate and transparent solution for intelligent academic recommendation services. [Methods] A generative framework for academic literature recommendation is developed. First, LLMs are employed to extract deep semantic features from academic papers and create a heterogeneous academic graph. Second, an optimized retrieval strategy is used to efficiently identify candidate papers, which are then semantically re-ranked by jointly leveraging the semantic understanding capabilities of LLMs and graph information. Finally, a path-based explainability mechanism is introduced to provide in-depth explanations of the recommendation results. [Results] Experiments on three academic datasets, namely WoSCite, CiteULike, and ICF, demonstrate that, under different Top-N settings, the proposed framework achieves an average relative improvement of at least 12.3% in precision and 11.3% in recall over the best-performing baseline models across the three datasets. In addition, the average overall score in the explainability evaluation increases from 5.6 to 7.2. [Limitations] The proposed framework incurs relatively high computational and storage costs in the construction and retrieval of heterogeneous academic graph. Moreover, it currently relies on static user-interest modeling and thus requires further optimization to broaden its applicability. [Conclusions] The proposed framework effectively improves the accuracy and explainability of academic literature recommendation, providing a practical and technically feasible pathway for the intelligent transformation of academic information services.

[Objective] To address the low accuracy of multi-step reasoning in visual question answering (VQA), this study enhances large language model (LLM) reasoning by incorporating external knowledge and optimizing prompting strategies. [Methods] We propose a knowledge-based VQA model, KRLP. The model employs the PromptCap captioning framework to generate image captions, assisting the LLM in understanding region-level visual information. It integrates two types of knowledge sources—open-domain knowledge retrieval and image-semantic knowledge retrieval—to enrich reasoning evidence. A new question decomposition strategy is designed to break complex questions into simpler sub-problems, thereby reducing reasoning difficulty. Context-relevant examples are constructed, and multiple reasoning outputs are aggregated to further improve answer accuracy. [Results] Experimental results show that KRLP achieves an accuracy of 67.2% on OK-VQA and 64.8% on A-OKVQA, outperforming the compared state-of-the-art methods. Ablation studies further confirm the effectiveness of each module in the proposed framework. [Limitations] The question decomposition module introduces additional computational and time overhead, resulting in lower efficiency when handling relatively simple VQA tasks. [Conclusions] By leveraging optimized LLM-based reasoning for knowledge-based VQA, the KRLP model offers a new approach for multi-step reasoning in knowledge-intensive visual question answering.

[Objective] To address the challenges of the low utilization of unstructured data and the fragmentation of spatio-temporal features across multi-source information in current telecom network fraud risk prevention and control, this study proposes a method for constructing spatio-temporal knowledge graphs based on large language model (LLM) fine-tuning and multi-agent collaboration. [Methods] Using more than 420,000 case records from a certain province over the past five years, this study first established a professional terminology database for the public security domain. Low-Rank Adaptation (LoRA) technology was then employed to fine-tune the DeepSeek model on multiple tasks, improving its capability to extract critical elements from telecom network fraud cases. Subsequently, a multi-agent collaborative framework was designed, comprising preprocessing, element extraction, conflict detection, and integration agents; the framework parsed unstructured text through dynamic prompt templates and a logical rule engine. Finally, a spatio-temporal knowledge graph with coupled heterogeneous features was constructed for telecom network fraud risk prevention and control. [Results] Experimental results demonstrate that the fine‑tuned model attains a BLEU-4 score of 49.718 and an average F1-score of 0.896 in element extraction. Moreover, the spatio-temporal knowledge graph constructed from text data of various types of telecom network fraud cases achieves a coverage rate of 0.979. [Limitations] Constrained by the unstructured and semantically fragmented nature of the critical elements of network behaviors, the current fine-tuned model exhibits a certain convergence ceiling, and its recognition capability for network behaviors still requires further improvement. [Conclusions] The construction method for the spatio-temporal knowledge graph of telecom network fraud risk prevention and control integrates the critical elements of multiple types of cases in a structured manner and can effectively restore criminal paths. The constructed knowledge graph provides solid data support for criminal pattern mining and targeted publicity and prevention.

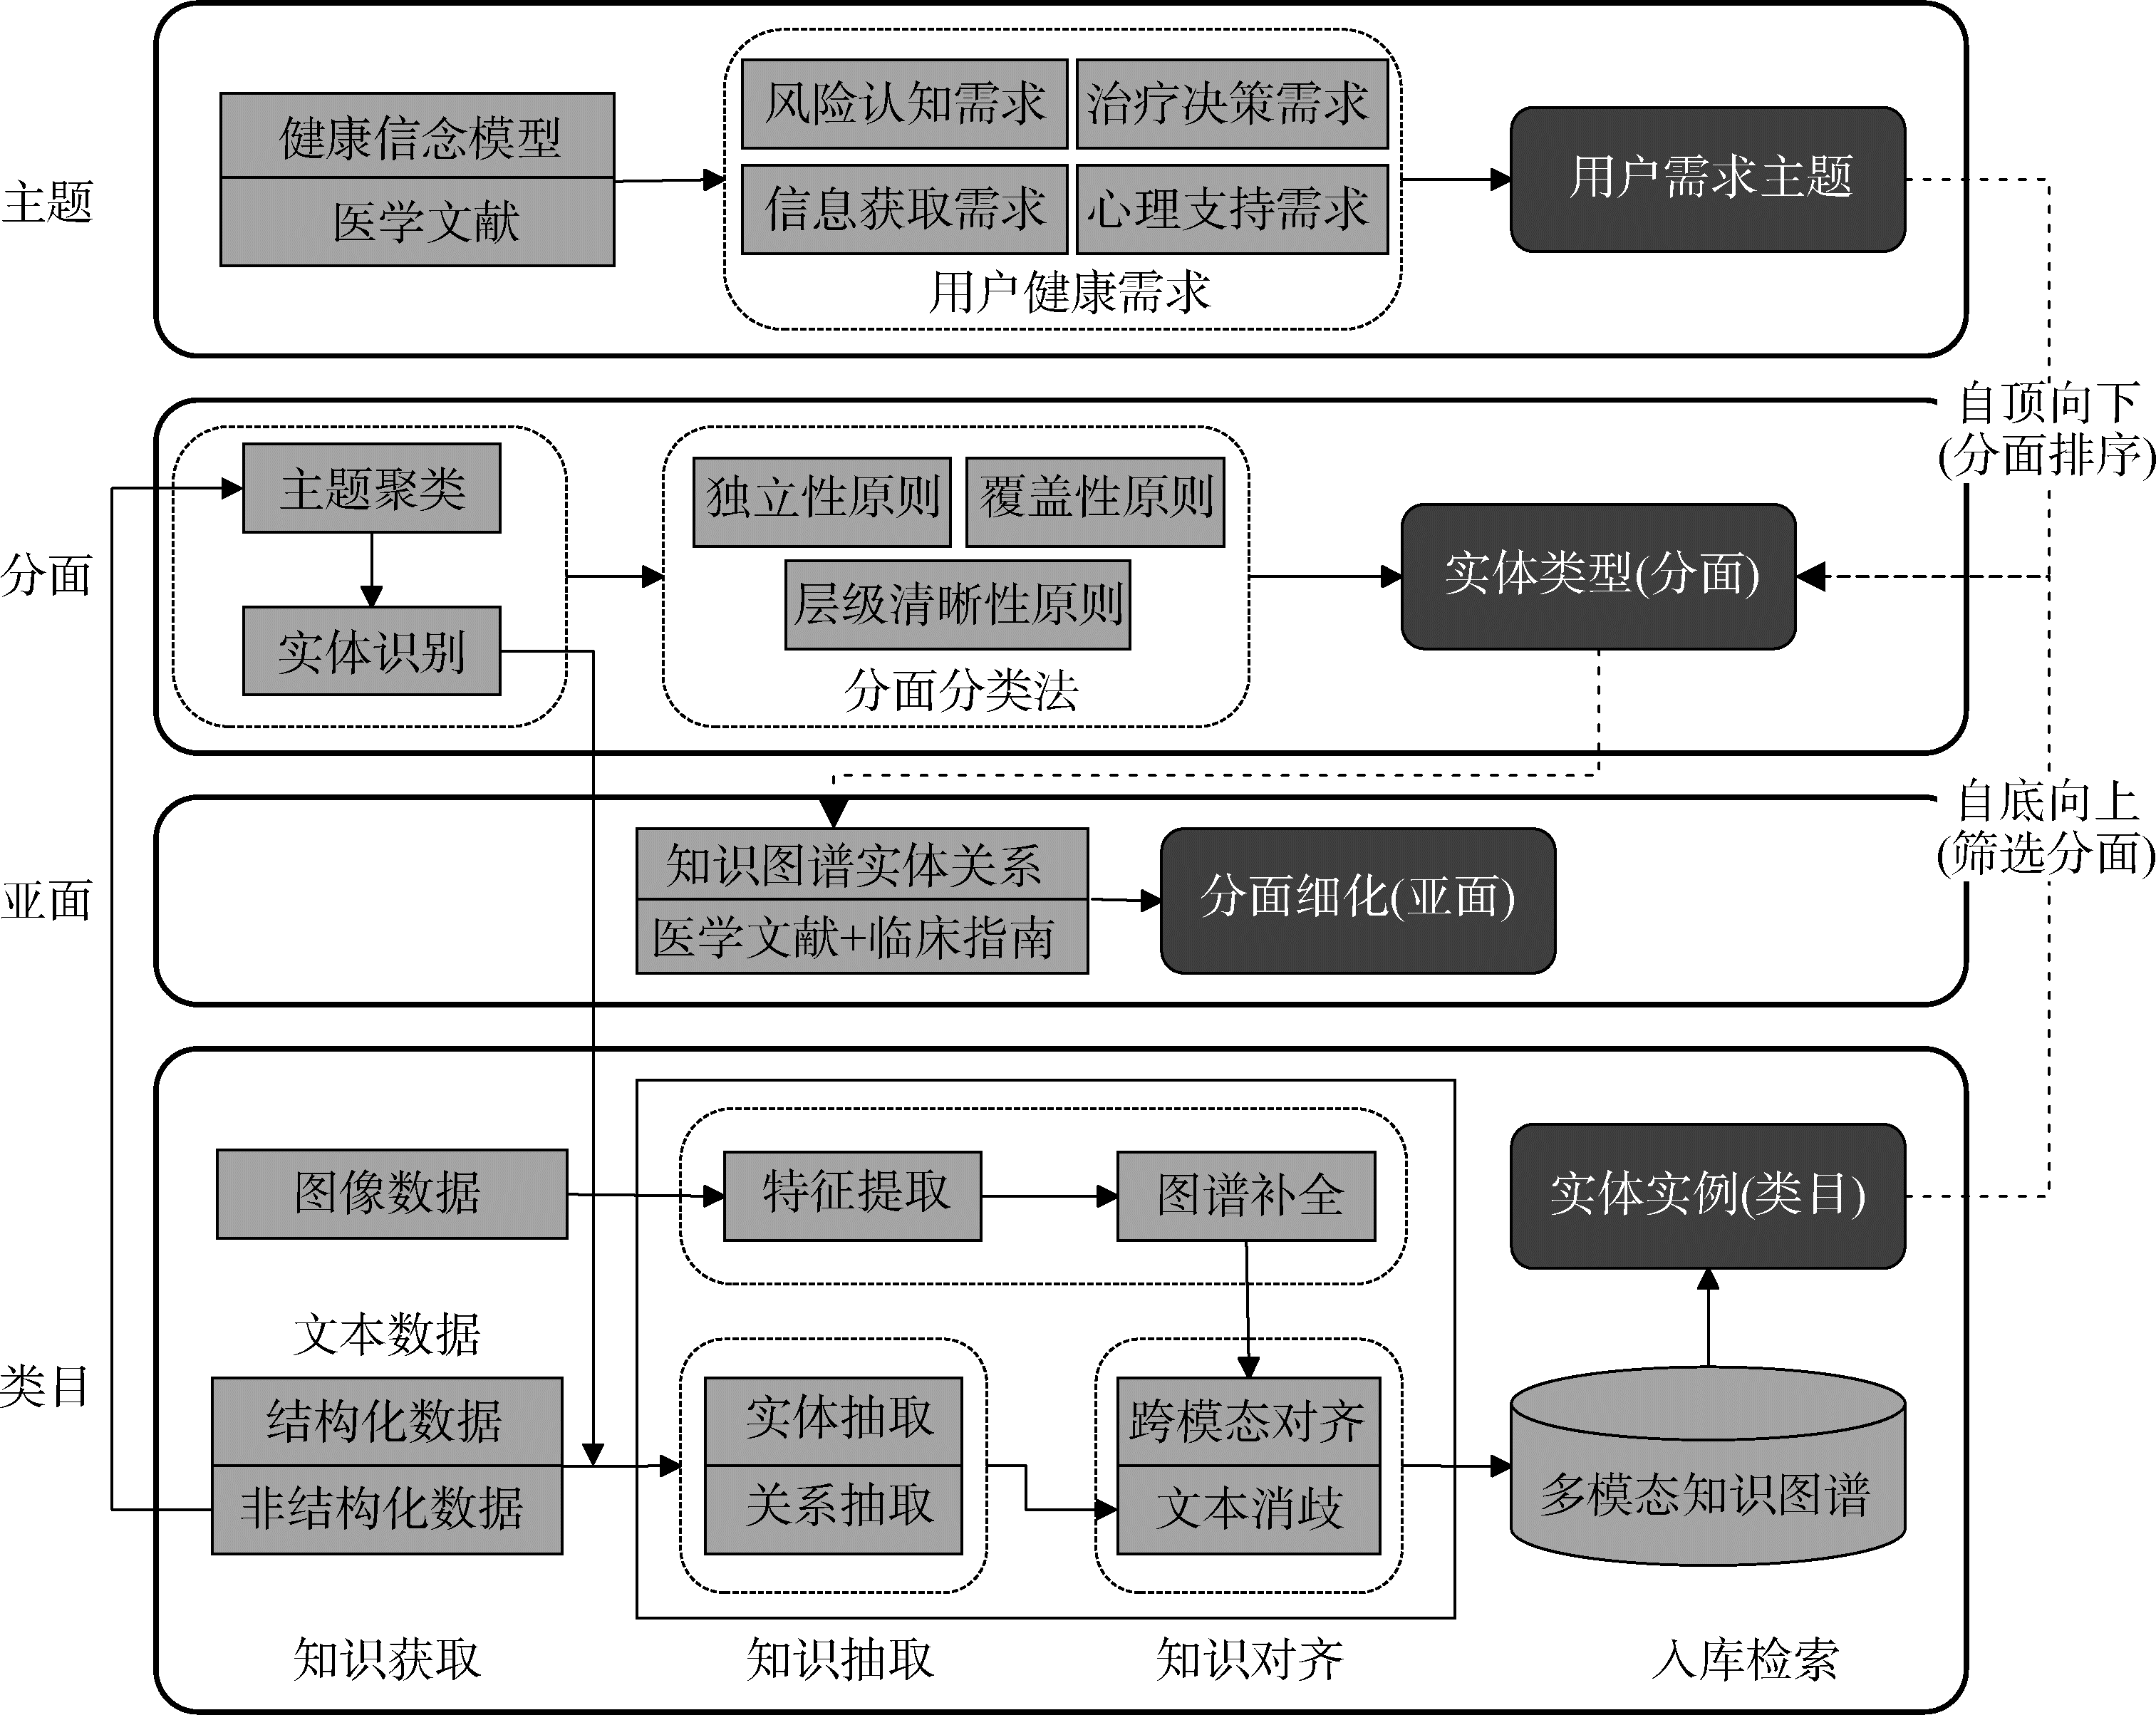
[Objective] This study develops a faceted retrieval framework based on multimodal semantic understanding to address limited retrieval precision and insufficient use of multimodal data in existing online medical Q&A communities, and to improve the organization of information in skin disease Q&A communities. [Methods] A Latent Dirichlet Allocation (LDA) topic model was used for text clustering, BERT-BiLSTM-CRF for entity recognition, and ResNet-50 for image feature extraction. Cross-modal alignment was used to establish semantic links between text and images and construct a multimodal knowledge graph. Guided by the Health Belief Model, three themes of user needs were identified and incorporated into a four-level hierarchy of themes, facets, subfacets, and categories. A faceted retrieval prototype was developed using text and image data from the vitiligo section of Youlai Doctor, and its search results were compared with those of other websites. [Results] The multimodal knowledge graph for skin diseases comprised 12 entity types, 15 semantic relation types, 5851 entity nodes and 11,549 relations. The faceted hierarchy comprised three themes, nine facets, and 11 subfacets. The comparison showed that the prototype’s search results better met user needs in terms of page presentation, information organization, and result relevance. [Limitations] The evaluation criteria for faceted retrieval were relatively limited, and the empirical comparison relied primarily on qualitative analysis. [Conclusions] By combining bottom-up topic aggregation with top-down analysis of user needs, this study developed a multilevel faceted knowledge organization framework that can effectively alleviate information overload in skin disease Q&A communities and improve retrieval precision and the use of multimodal data.
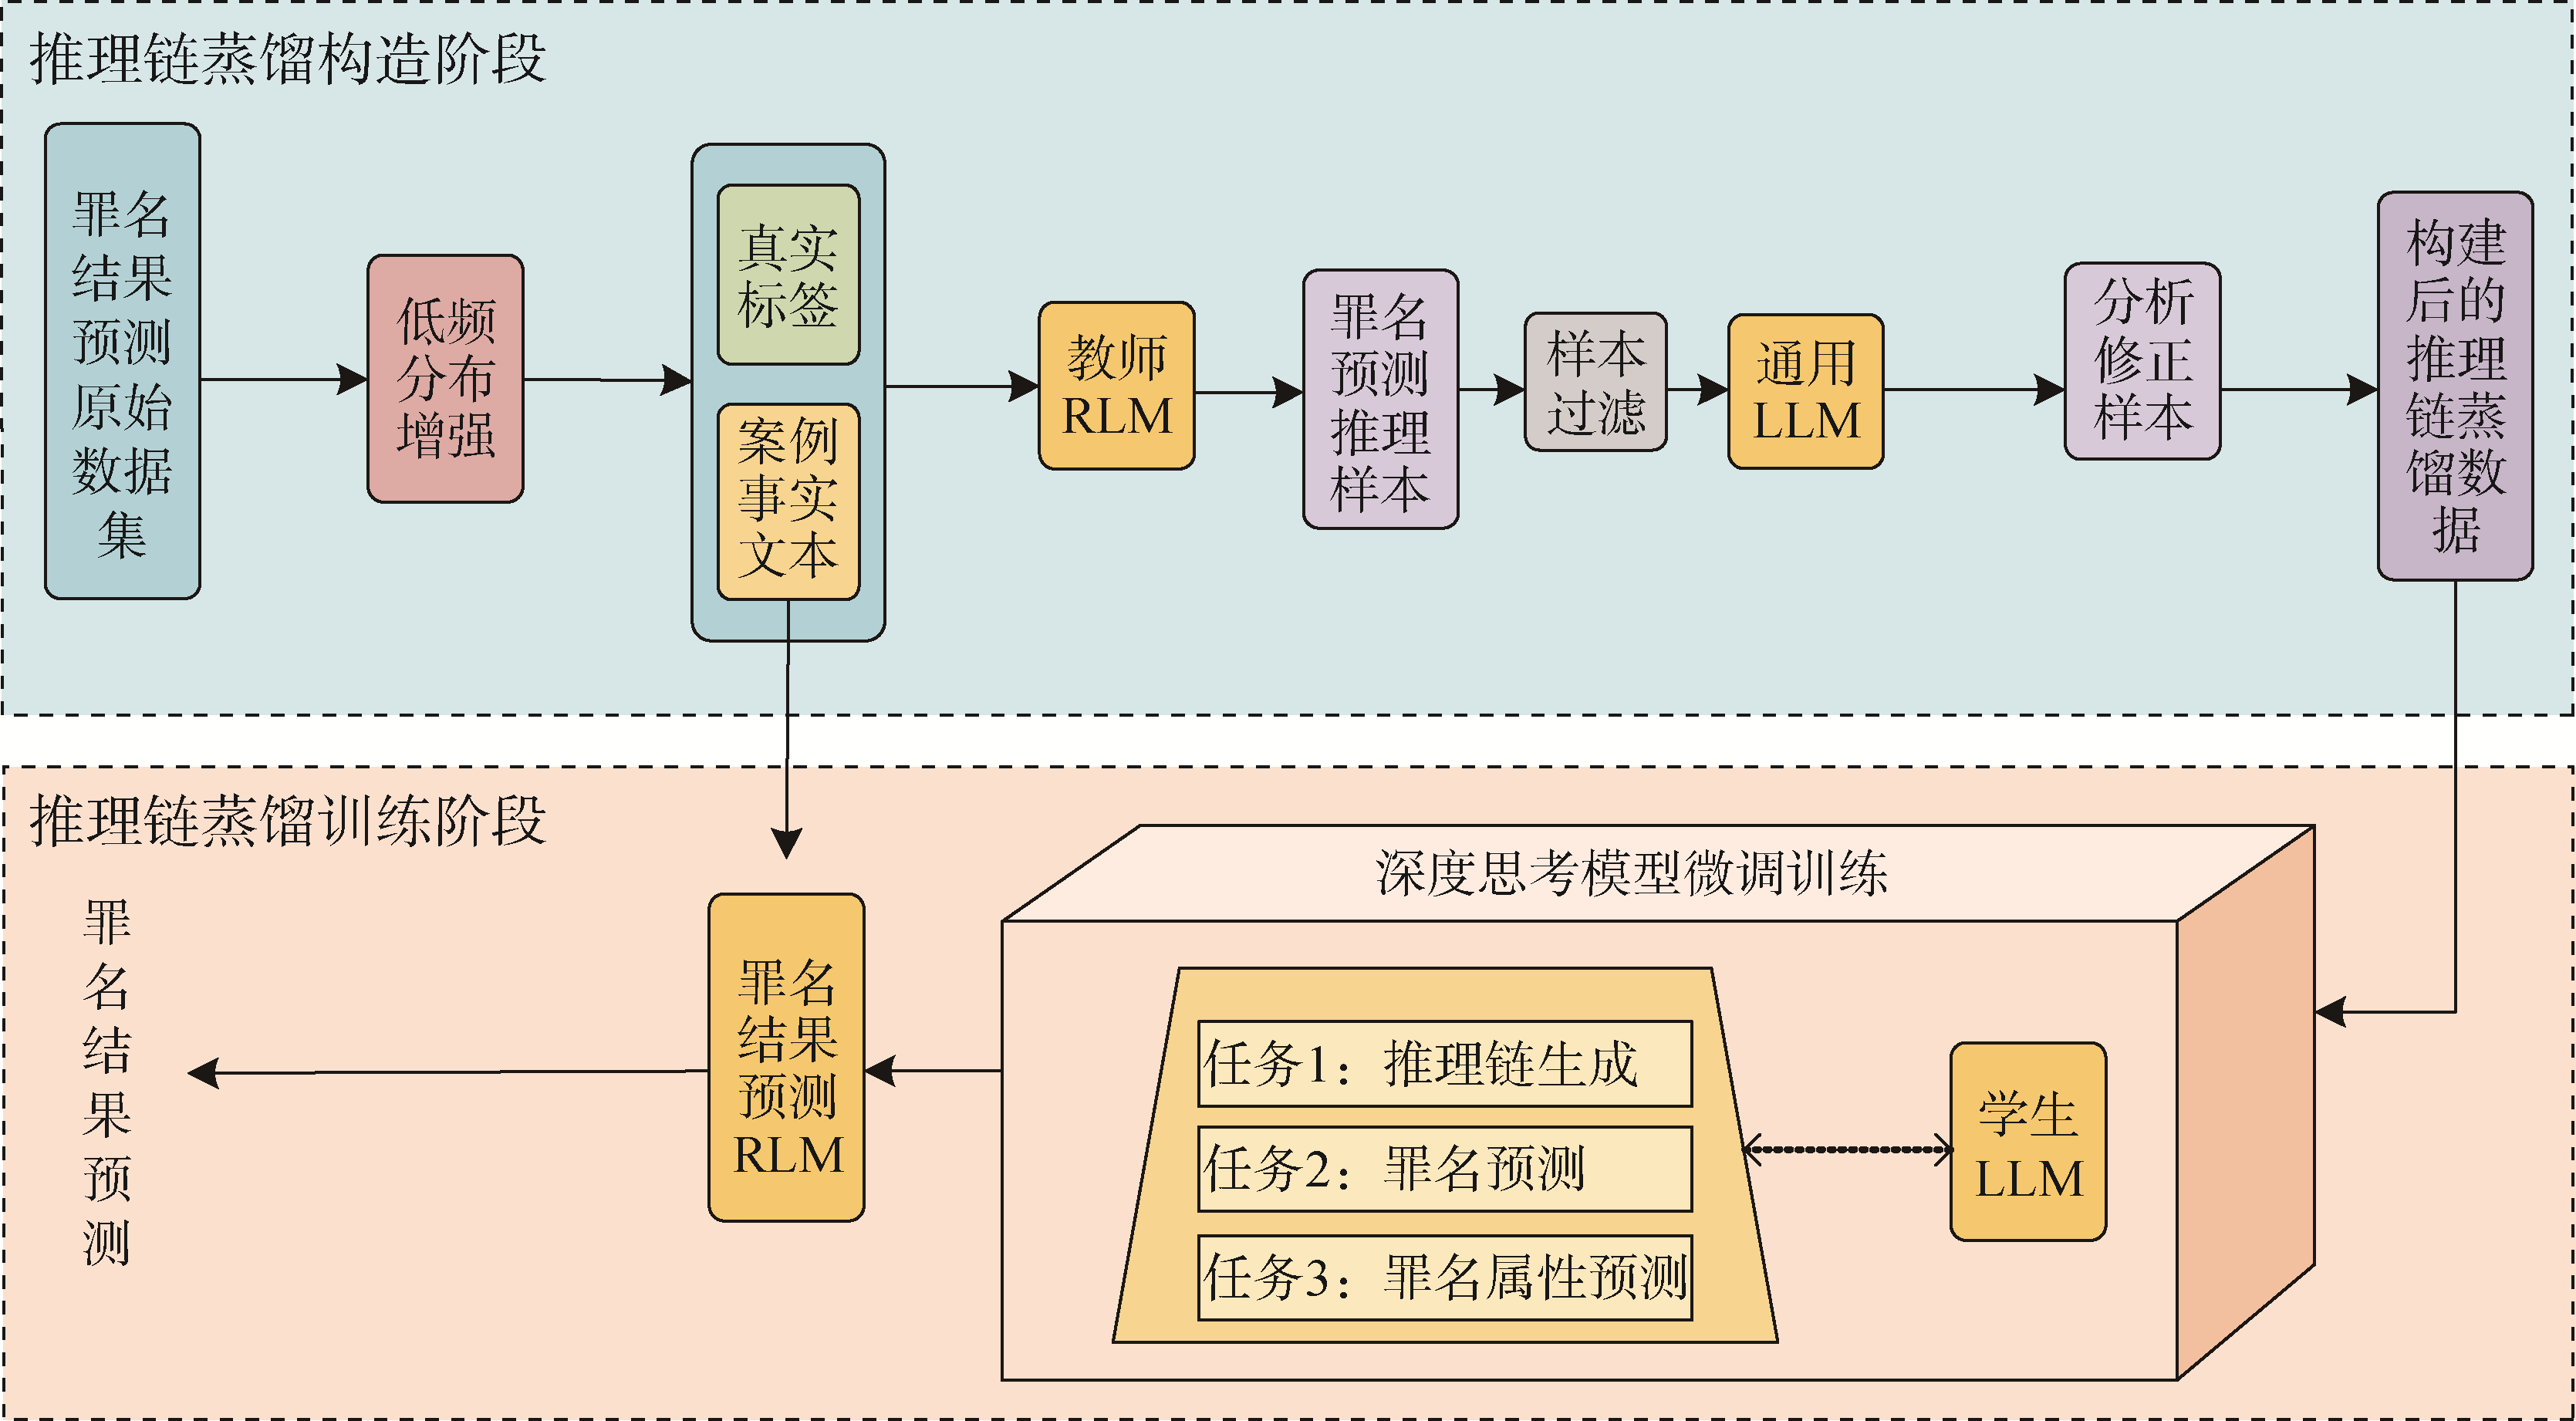
[Objective] This study proposes a reasoning-chain distillation framework based on large language models (LLMs) to train a new model capable of multi-task deep reasoning for legal charge prediction in judicial proceedings. [Methods] We first employ a reasoning-capable teacher model to construct a deep reasoning distillation dataset, which is then verified and refined through a large language model workflow. The student model is subsequently trained to learn both the reasoning process and the final prediction results for charges. [Results] The JudgMind-Distill model trained with our method outperforms the best-performing baseline on the Criminal-S dataset for charge prediction, achieving performance exceeding that of the 671B-parameter teacher model, despite having only 7B parameters. Specifically, it improves the F1 score by 0.2 percentage points in charge prediction and by 18.3 percentage points in charge attribute prediction. [Limitations] The model does not yet account for the added complexity of cases involving multiple defendants or multiple charges. [Conclusions] This paper presents a training method for LLMs on charge prediction. It converts the teacher model’s reasoning chains into supervision signals for finetuning, improves charge prediction accuracy and interpretability while retaining a smaller parameter scale and higher inference efficiency, offering a feasible route for lightweight charge prediction in judicial scenarios.